Technology
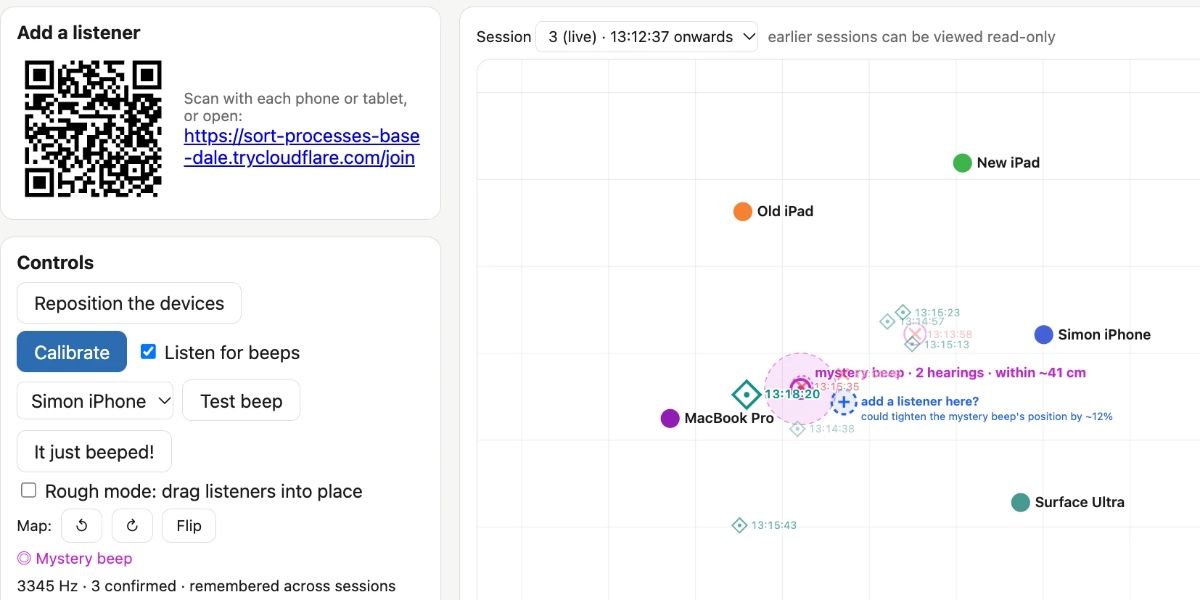
Locating the source of a mysterious beep
By Marcus Chen
Advertisement · Why this ad?
Katherine oversees editorial operations across all six brands. Before joining The Meridan Group, she spent 14 years at the Minneapolis Star Tribune, where she led the metro desk through its digital transformation. She holds a Master's in Journalism from Northwestern's Medill School.
More from Katherine →
Today, we're introducing Muse Ember, our smallest and most efficient model designed for complex reasoning execution and the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing. Muse Ember delivers more intelligence per dollar than Claude Haiku 5.5 or GPT-6 Luna at any reasoning setting: it matches Haiku's best score at about a third of the cost and beats every Luna setting. It also sits on the efficiency frontier of the full Artificial Analysis leaderboard: no model scores higher for less per task. Intelligence vs. Cost Per Task Artificial Analysis Intelligence Index against cost per task at each reasoning effort, from the raw Artificial Analysis results. Muse Ember costs are estimates at proposed pricing. Intelligence vs. Cost Per Task $0.00 $0.10 $0.20 $0.30 $0.40 15 20 25 30 35 40 Cost Per Task (USD) Artificial Analysis Intelligence Index xhigh max medium high xhigh max high xhigh max Muse Ember Claude Haiku 5.5 GPT-6 Luna Intelligence vs. Cost Per Task $0.00 $0.10 $0.20 $0.30 $0.40 15 20 25 30 35 40 Cost Per Task (USD) Artificial Analysis Intelligence Index xhigh max medium high xhigh max high xhigh max Muse Ember Claude Haiku 5.5 GPT-6 Luna xhigh max medium high xhigh max high xhigh max Muse Ember Claude Haiku 5.5 GPT-6 Luna Intelligence vs. Cost Per Task: Intelligence vs. Cost Per Task Series Measurement Value Muse Ember Cost Per Task (USD) $0.116 Muse Ember Score 33.9 Muse Ember Cost Per Task (USD) $0.136 Muse Ember Score 35.8 Claude Haiku 5.5 Cost Per Task (USD) $0.092 Claude Haiku 5.5 Score 24.6 Claude Haiku 5.5 Cost Per Task (USD) $0.159 Claude Haiku 5.5 Score 29.6 Claude Haiku 5.5 Cost Per Task (USD) $0.248 Claude Haiku 5.5 Score 34.3 Claude Haiku 5.5 Cost Per Task (USD) $0.411 Claude Haiku 5.5 Score 36.2 GPT-6 Luna Cost Per Task (USD) $0.073 GPT-6 Luna Score 21.4 GPT-6 Luna Cost Per Task (USD) $0.104 GPT-6 Luna Score 23.3 GPT-6 Luna Cost Per Task (USD) $0.152 GPT-6 Luna Score 27.8 Muse Ember evaluation results Muse Ember evaluation results: Evaluation results Evaluation results Featured model. Muse Ember (max) Claude Haiku 5.5 (max) GPT-6 Luna (max) Agents AutomationBench-AA E2E business workflows Best result. 37.8 13.9 20.2 Agents' Last Exam End-to-end agent tasks Best result. 61.6 57.0 57.1 Personal Superintelligence Index Internal composite index of personal and knowledge work Best result. 46.8 36.1 37.0 Coding Terminal-Bench 4.0 Agentic terminal coding, best published harness Best result. 40.9 39.2 16.4 Coding Agent Index-AA Coding in real agent harnesses Best result. 46 37 31 FrontierCode 2.0-AA Real engineering tasks judged on mergeability 27.2 Best result. 34.9 25.2 Multimodal GDP.pdf-AA Professional work over long documents Best result. 22.8 20.8 Best result. 22.8 OSWorld 2.1 Computer use across desktop apps Best result. 69.5 (partial) 33.8 (binary) 68.9 (partial) 27.8 (binary) 50.5 (partial) 17.0 (binary) PerceptionBench (w/ tools) Fine-grained visual perception Best result. 80.6 78.6 62.8 General Artificial Analysis Index Best result. 36 Best result. 36 28 For more details about our evaluations, see our report . Muse Ember is available today on the Meta Model API, at $0.10 per million input tokens and $0.50 per million output tokens. In early testing, our partners put Muse Ember to work on the kinds of tasks agents repeat all day, from reviewing contracts to writing code. Box Cline Oracle Cloudflare You.com Box Previous slide Next slide “ On the Box AI Complex Work Eval, Muse Ember delivers impressive accuracy, speed and token efficiency. It can score a contract against a company's negotiation playbook clause by clause and land on the right overall risk rating, or screen candidates against a detailed brief and flag the borderline ones who still qualify as alternates. Muse Ember is a fast, efficient foundation for agents doing real work on enterprise content. ” “ It's incredible seeing Meta release a lightweight model for developers who want a fast, low-cost model they can rely on, and for teams cutting costs by running it as the subagent in their harness. Muse Ember is purpose-built for, and excels at, subagent work like coding and document analysis. ” “ Muse Ember showed an encouraging ability to tackle complex engineering tasks in our early testing. We see strong potential for it to become a valuable tool for engineering teams. ” “ What stood out in our testing was speed. Muse Ember ran up to 30% faster at the tail than the comparable model we tested, and it handled broad, multi-repo investigation tasks well. It’s a strong fit for fast, high-throughput agentic workloads. ” “ Muse Ember completed every coding quest in our testing with the lowest latency of any model we tested: a p95 of 2.2 seconds, about 4x to 13x faster than leading open-weight models, and with 36–48% fewer output tokens. We’re excited about what Meta Superintelligence Labs is building next and about bringing it to our customers. ” Agents Agents spend most of their tokens on many small, structured steps, and Muse Ember is built for exactly that. It can carry a business workflow end to end, pulling records, calling tools in sequence, and updating systems across apps. With a 1M-token context window and up to 512K output tokens, it can take in a full codebase or document set in a single call. AutomationBench-AA AutomationBench-AA results at max reasoning, reproduced from the doc's current chart.. Score AutomationBench-AA Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% Score 37.8% 20.2% 13.9% AutomationBench-AA Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% Score 37.8% 20.2% 13.9% AutomationBench-AA: AutomationBench-AA Series Measurement Value Muse Ember (max) Model Muse Ember (max) Muse Ember (max) Score 37.8% GPT-6 Luna (max) Model GPT-6 Luna (max) GPT-6 Luna (max) Score 20.2% Claude Haiku 5.5 (max) Model Claude Haiku 5.5 (max) Claude Haiku 5.5 (max) Score 13.9% Agents' Last Exam Agents' Last Exam results at max reasoning, reproduced from the doc's current chart.. Score Agents' Last Exam Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% 50% 60% 70% Score 61.6% 57.1% 57.0% Agents' Last Exam Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% 50% 60% 70% Score 61.6% 57.1% 57.0% Agents' Last Exam: Agents' Last Exam Series Measurement Value Muse Ember (max) Model Muse Ember (max) Muse Ember (max) Score 61.6% GPT-6 Luna (max) Model GPT-6 Luna (max) GPT-6 Luna (max) Score 57.1% Claude Haiku 5.5 (max) Model Claude Haiku 5.5 (max) Claude Haiku 5.5 (max) Score 57.0% Personal Superintelligence Index Personal Superintelligence Index results at max reasoning, reproduced from the doc's current chart.. Score Personal Superintelligence Index Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% 50% Score 46.8% 37.0% 36.1% Personal Superintelligence Index Muse Ember (max) GPT-6 Luna (max) Claude Haiku 5.5 (max) 0% 10% 20% 30% 40% 50% Score 46.8% 37.0% 36.1% Personal Superintelligence Index: Personal Superintelligence Index Series Measurement Value Muse Ember (max) Model Muse Ember (max) Muse Ember (max) Score 46.8% GPT-6 Luna (max) Model GPT-6 Luna (max) GPT-6 Luna (max) Score 37.0% Claude Haiku 5.5 (max) Model Claude Haiku 5.5 (max) Claude Haiku 5.5 (max) Score 36.1% Coding Muse Ember is built for the coding subtasks an agent sends off hundreds of times a session: reading files, running tests, making targeted fixes. Terminal-Bench 4.0 Terminal-Bench 4.0 results at max reasoning, reprod